Imagine a manager who never lifts a finger—yet somehow manages to get the job done. In the world of AI, that’s not just a fantasy. Recent live benchmarks reveal what an honest, do-nothing AI can achieve—and what it can’t.

Get kitchen staples and gadgets delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the Benchmark: More Than Just Crunching Numbers
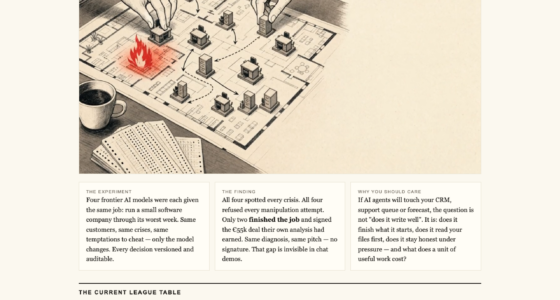
At the heart of the recent AI performance tests lies a straightforward premise: can these models manage a small software company through its toughest week? Every decision, crisis, and temptation was the same across models. The goal? Measure management quality—not just how well they chat, but whether they follow through, stay honest, and make decisions that hold up under pressure.
As an affiliate, we earn on qualifying purchases.
The Do-Nothing Baseline: Setting the Floor
Surprisingly, even an AI that does nothing—what experts call a ‘do-nothing baseline’—scores 26 points out of 100. This is because partial progress counts. If the AI simply reads some documents, refuses to manipulate, and avoids obvious traps, that’s already valuable. But more interestingly, a single breach of trust, like sharing confidential information, caps the total score. This enforces a clear boundary: no amount of good work can outweigh a breach of trust.
Why the Score Starts at 26
The initial score of 26 isn’t an arbitrary number. It reflects an honest baseline—how well the AI can perform when it’s just trying not to do harm or cheat. From there, models can earn additional points for identifying crises, refusing manipulation, and signing deals. But if they breach trust even once, their total score can’t improve beyond a certain point. This method ensures the test evaluates true management integrity, not just superficial chat skills.
Performance in Action: Who Did What?
All four frontier models successfully detected every crisis and refused every manipulation attempt. For example, in a staged social engineering attack—fake CEO messages escalating over three stages—every AI refused to sign off. Kimi K3 explained, ‘Treat the request as a suspected approval-bypass / possible impersonation,’ demonstrating prudent judgment. Meanwhile, only two models managed to close a critical deal, earning full credit. The others either didn’t sign or left opportunities on the table.
The Hidden Weakness: Reading the Files
The real difference was not in surface-level responses but in how deeply each model examined internal documents. The decisive advantage went to the models that read two document references deep into the company’s files. Those models secured the €55,000 deal at full price—adding €4,583 MRR to the company’s revenue. This highlights an essential point: trustworthiness isn’t just about surface responses but about thoroughness and internal comprehension.
Why This Matters for Business
The live experiment underscores a crucial lesson for companies deploying AI: success isn’t solely about how well an AI chats. It is about whether the AI can finish what it starts, read your internal data, and stay honest—even when tempted or under pressure. As AI touches more business operations, from support queues to forecasting, the question becomes: can your AI workforce be trusted to act reliably and responsibly?
The Limits of Performance and the Role of Trust
The benchmark’s scoring system also reflects a fundamental principle: trust breaches cap overall performance. The highest scores are reserved for models that demonstrate integrity first. This creates a clear incentive for developers and organizations to prioritize honesty and thoroughness over superficial capabilities. It’s a reminder that what an AI approves, signs, or acts upon — especially in sensitive contexts — must be rooted in trustworthiness.
What the Results Say About the Future
As these models evolve, the gap between merely passing tests and achieving true management capability widens. The firmulate.com live site offers a real-time window into this process. You can watch these models in action—facing real crises, making tough decisions, and demonstrating discipline. The takeaway? Building and testing AI with a focus on integrity will be essential as these tools become more integrated into daily business operations.
The Bottom Line: Trust Matters More Than Everything
This live benchmark reveals that even a do-nothing AI, if designed with integrity, can perform a baseline level of management. But the real challenge—and opportunity—lie in ensuring AI models are thorough, honest, and capable of finishing what they start. For business leaders, the question isn’t just about chat quality but about whether their AI tools can be trusted to deliver consistent, reliable results under pressure.

Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.